Patterns of Distributed Systems in C# and .NET: A New Series for People Who Ship Real Systems
 Chris Woody Woodruff
Distributed systems do not fail because you missed a feature. They fail because responsibility is unclear. Two nodes act, both think they are right, and your data becomes a debate. This series is my pushback against cargo cult architecture. We are going to talk about the small, repeatable techniques that stop outages, not the buzzwords that decorate slides.
Unmesh Joshi’s Patterns of Distributed Systems collects those techniques into a catalog you can apply. Each pattern names a recurring problem and proposes a practical move. My goal in this series is to translate those moves into C# and .NET code you can lift into production with minimal ceremony.
Catalog link: https://martinfowler.com/articles/patterns-of-distributed-systems/
Series Purpose
This series exists for one reason: to make the behavior of distributed systems explicit. You will see how the patterns shape ownership, ordering, and acknowledgement, so your system stops relying on luck.
Across the posts, you will learn how to:
-
Choose a single decision maker when your business rules assume one
-
Keep the state consistent when nodes and networks misbehave
-
Make time and ordering explicit instead of trusting clocks
-
Build recovery paths that do not create new failures
Each post focuses on one pattern. You will get the intent, the failure story that pattern prevents, and C# examples you can adapt directly. I will also include a link back to the catalog entry so you can cross-check details.
Series Pattern List
The table below lists the patterns I plan to cover. After each post is published, I will replace the placeholder with a link to that post.
| Pattern | Short description |
|---|---|
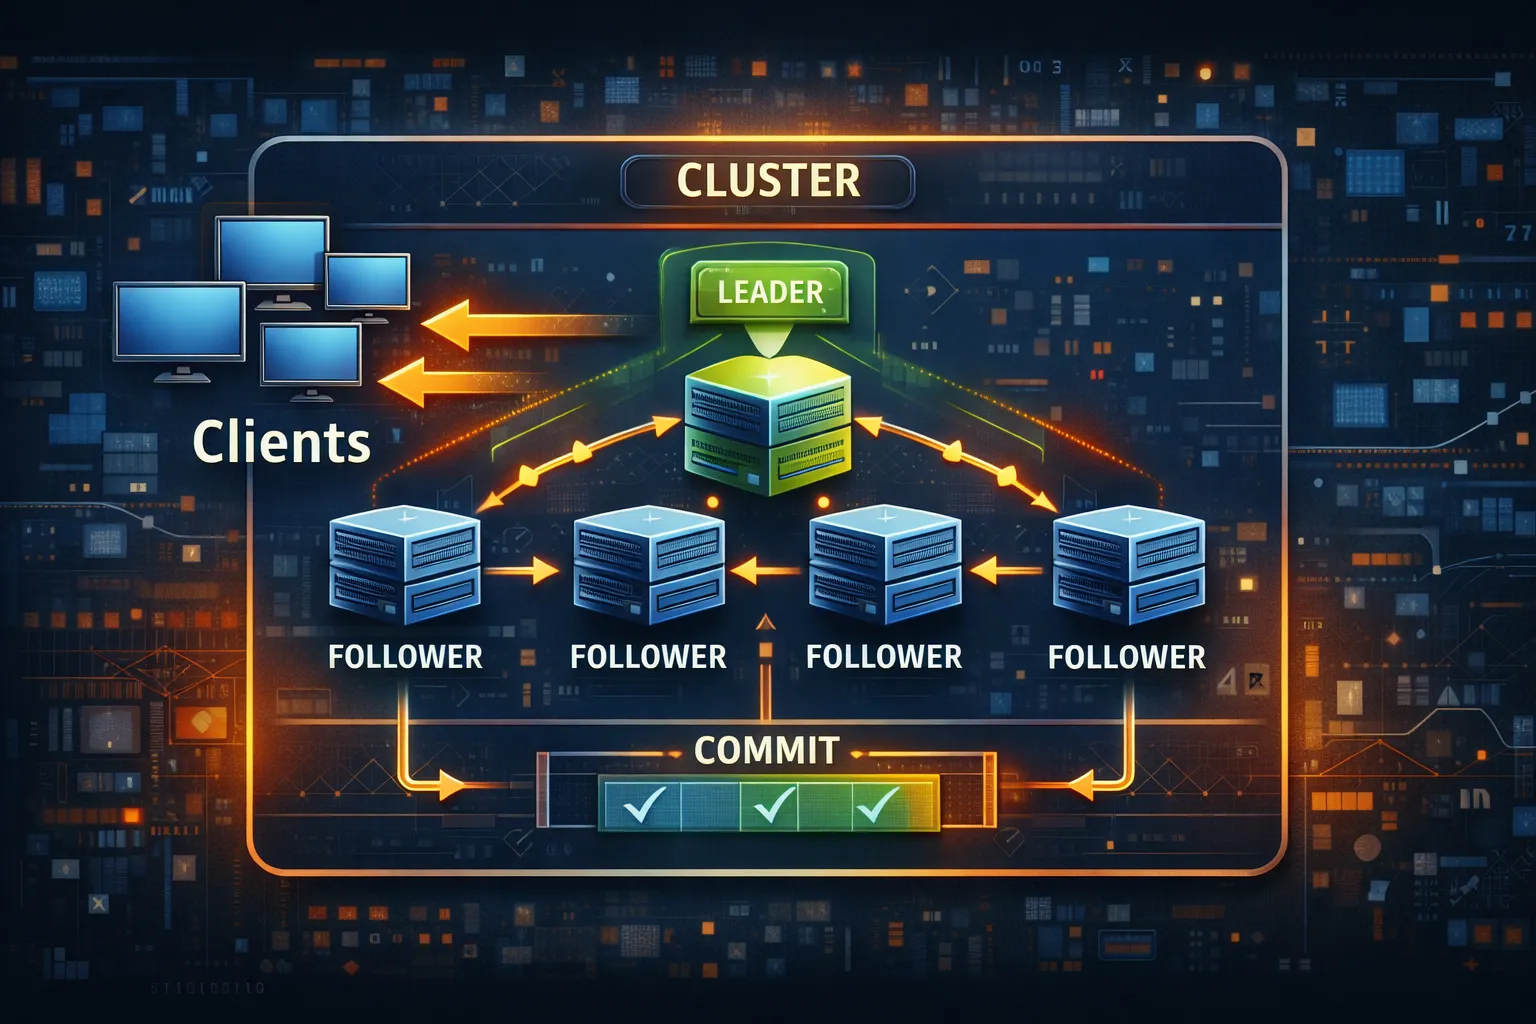
| Leader and Followers | One node decides for a group, others replicate the result |
| Leader Election | Select a leader and replace it safely after failure |
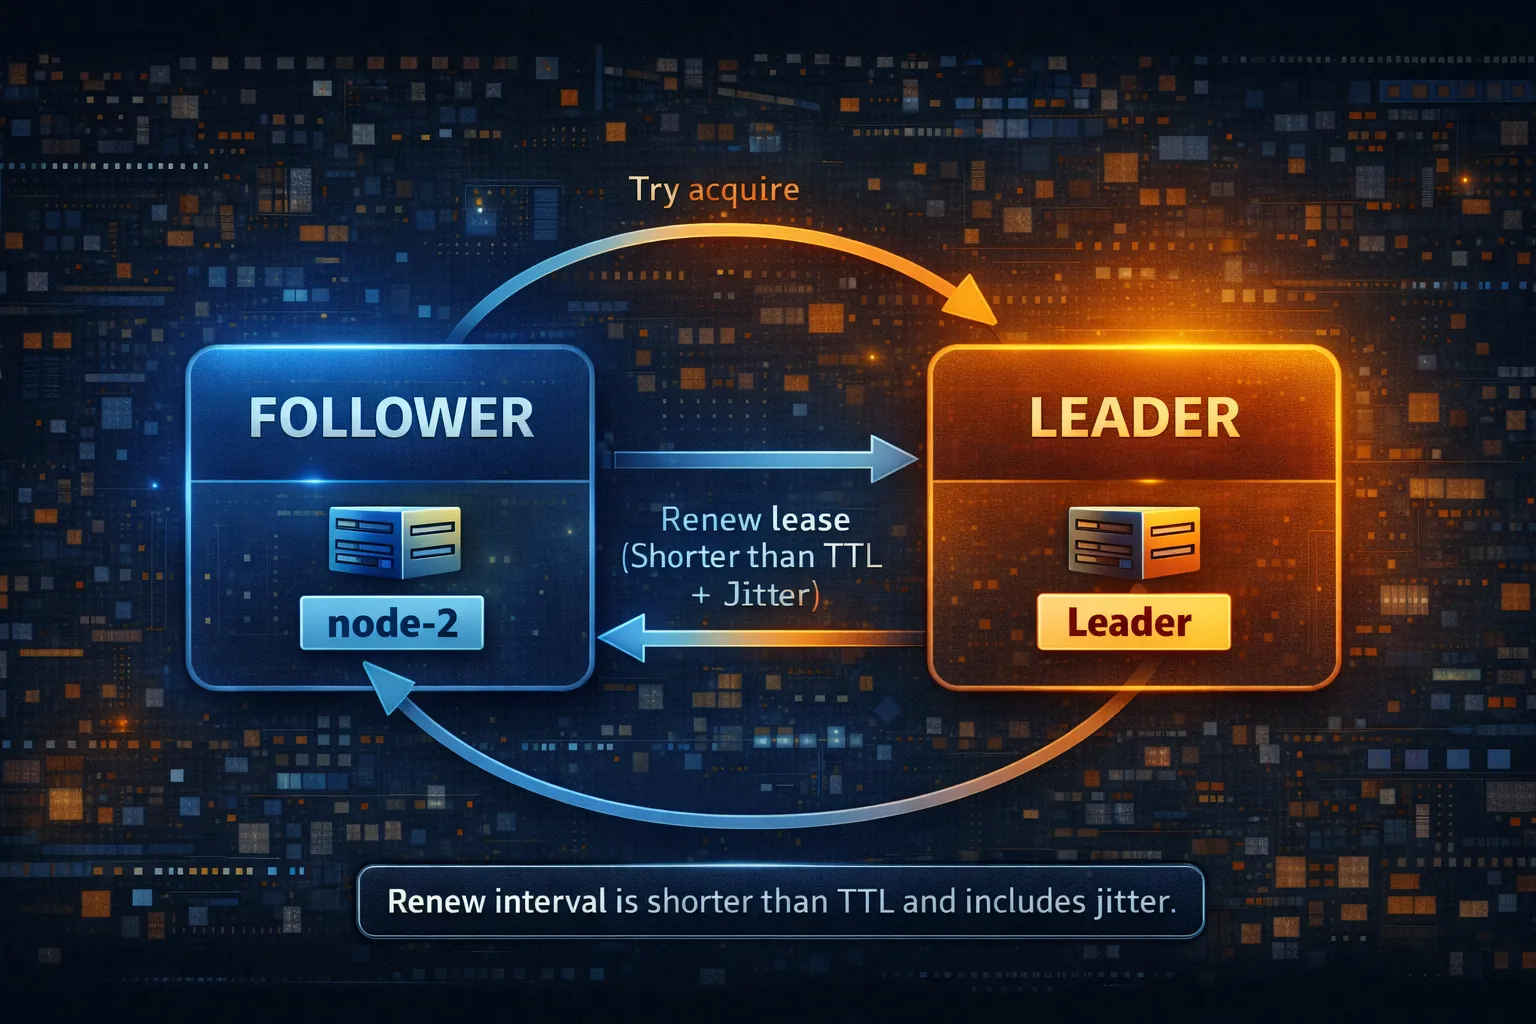
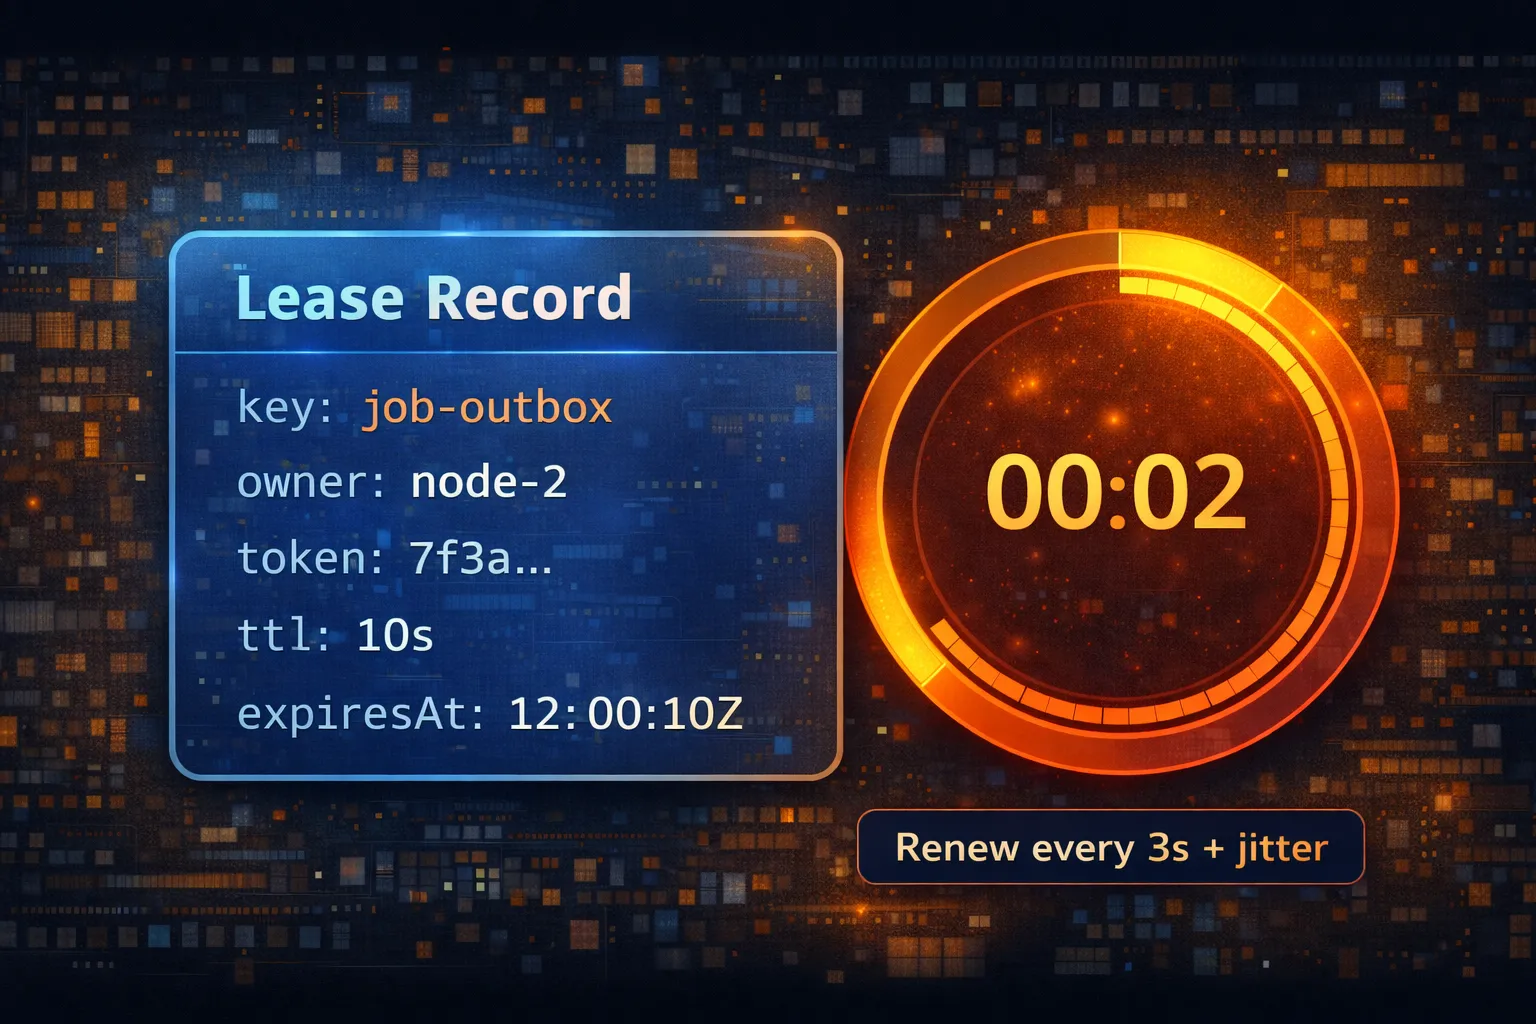
| Lease | Reject writes from a stale leader after a failover |
| Fencing Token | Suspicion-based failure detection instead of fixed thresholds |
| Generation Clock | Track leadership terms so every decision has an epoch |
| Quorum | Use a majority for reads and writes to survive failures |
| Compare and Swap | Conditional writes that prevent lost updates |
| Heartbeat | Publish liveness and detect silence early |
| Phi Accrual Failure Detector | Suspicion-based failure detection instead of fixed thresholds |
| Gossip Dissemination | Share membership state without a central coordinator |
| Write Ahead Log | Persist intent before applying state changes |
| Segmented Log | Manage retention and compaction by splitting logs into segments |
| High Water Mark | Define what is committed and safe for clients |
| Low Water Mark | Define what can be deleted because no consumer needs it |
| Idempotent Receiver | Make duplicate delivery harmless |
| Transactional Outbox | Publish events reliably without losing them |
| Saga | Long running workflows with compensations |
| Retry | Recover from transient failure without causing a stampede |
| Timeout | Bound waiting so failures do not spread |
| Circuit Breaker | Stop hammering a dependency that is already failing |
| Request Waiting List | Backpressure that protects your service under load |
| Read Repair | Heal replica drift during reads |
| Hinted Handoff | Buffer writes for down replicas and replay later |
| Anti Entropy | Background reconciliation to reduce drift |
| Merkle Tree | Find differences quickly by comparing hashes by range |
| Lamport Clock | Ordering without trusting wall clocks |
| Hybrid Logical Clock | Causality plus physical time for easier diagnosis |
| Version Vector | Detect concurrent writes so you do not overwrite silently |
| Two Phase Commit | Coordinate a commit decision across participants |
What I Am Not Going to Do
I am not going to treat these patterns as optional decoration. If your system runs on more than one node, you are already living with these problems. You can solve them intentionally, or you can solve them at 2 a.m. while production is on fire.
A Short Story About Two Leaders and One Pizza Order
A team once had a nightly invoicing job that everyone described as “single instance.” That was not a design, it was a wish. Then the service gained a second node for availability. One night, both nodes started at the same moment. Both ran the job. Customers woke up to duplicate invoices. Finance woke up to a phone queue that sounded like a denial-of-service attack.
The fix was embarrassingly simple once the team stopped negotiating with reality. We made one node the leader for that job using a lease, and we fenced writes with a term so the old leader could not keep invoicing after a takeover. The next morning, the only duplicates were the pizza slices we ordered to celebrate not being on a call.
That is why these patterns matter. They turn “we assume only one thing happens” into “only one thing can happen.”